LIVESIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - SIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - SIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - SIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - LIVESIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - SIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - SIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL - SIGNAL OVER NOISE - 375K+ FOLLOWERS ACROSS SOCIAL PLATFORMS - 18+ YEARS IN MARKETING - NEW AI DISPATCHES - NO HYPE, NO PAYWALL -
Matt’s picks · October 2026
5 Free AI Video Generators You Can Run Locally
Compare clip length, resolution, audio and realistic GPU requirements — with official downloads, setup docs and examples.
Run these models on your own hardware without a vendor charge for every render, subject to each model’s license. Your GPU, electricity, storage and time still matter. Hosted services and GPU rentals are separate, paid choices. These are free/local models, not all permissively licensed open source.
The short version
Choose the workflow, not just the model.
These are my editorial selections, not a measured cross-model benchmark. Clip examples, published ranges and hard maximums are different things. A long promotional montage is not one generation.
Five free/local video models: clip-length status, base versus later processing, and generated audio. See each model section for hardware and license evidence.
HD / Full HD involves a separate video super-resolution (VSR) stage.
Yes · synchronized audio
Swipe the comparison sideways, or read the full mobile-friendly sections below.
#1
Matt’s quality pick
MiniMax H3
Beautiful generations, complex action and visual consistency, with powerful reference controls and generated stereo audio. This is my quality preference, not a claim that it wins every physics task.
Extensions and stitched shots are separate from a first generated clip.
Base → later stages
768-pixel short edge; typical 1344 × 768
The official full 2K recipe adds hosted Context-IR and Regenerate stages. It is not a completely local 2K-base pipeline.
Generated sound
Yes · stereo
The two local-base examples below include generated stereo sound.
Reference controls. First/last-frame control uses FL2VA. Image, video and audio references use the appropriate Ref2VA workflow; the graphs are not interchangeable.
Community-tested configurations
Specific 16GB and 12GB GPU configurations exist; there is no universal consumer minimum here.
RTX 5080 16GB: pruned INT8, ~5.17-second 960 × 544 clips with audio. RTX 4070 12GB: a smaller 4B encoder through ClipProj, a character LoRA and offloading; about 40GB system RAM observed, plus shared GPU memory. This is not the full original encoder on 12GB.
The tradeoff. The trickiest pick to configure on constrained hardware. Offloading and changed components can make it fit, but cost time, RAM and potentially quality.
Official example · MiniMax
Local-base text to audio/video
H3-Base FL2VA · local 768p
Generated stereo soundtrack
Official reproducible local-base output, not a hosted-enhanced 2K sample.
Great for keeping a story flowing: generated audio, connected multi-shot scenes and first/last-frame control, with fast workflows for iteration. Distilled and quantized options offer different quality and speed tradeoffs.
Longer clips are workflow-dependent; a universal local hard maximum is not verified.
Base → later stages
960 × 544 in the reference two-stage example
2× latent refinement → 1920 × 1088, about Full HD. Separate high-resolution, tiled and DFR workflows also exist.
Generated sound
Yes
The multishot web preview below is silent; the second official example has an audio track.
Reference controls. Connected shots, first/last-frame control and audio conditioning, depending on the selected graph. Not every combination works in every workflow.
Quantization, distilled models and offloading can lower the working requirement. No universal 8GB or 12GB floor is established; encoder, frames, precision and graph all matter.
The tradeoff. A small, fast preview and a polished high-resolution result are different jobs. Extra refinement stages can mean more memory and more time.
Official example · LTX / Lightricks
Connected multishot showcase
LTX-2.5 · official multishot showcase
This published preview is silent
The model supports generated audio. This 6.12-second, 1920 × 1080 delivery file is an example, not a native-resolution or maximum-length specification.
An established ecosystem of LoRAs and workflows, plus a smaller 5B model that makes local video more approachable. Choose between that TI2V model and the separate, quality-oriented A14B branches.
5B: 121 frames / 24 fps. A14B: 81 frames / 16 fps. These are defaults, not proven hard caps.
Base → later stages
Up to 720p; 480p / 720p depends on checkpoint and workflow
An upscaled export is not native 1080p output.
Generated sound
No · silent base
Base T2V / I2V / TI2V does not generate a soundtrack. Launch-reel music is promotional audio.
Reference controls. TI2V-5B accepts text or an image. A14B has separate text-to-video and image-to-video checkpoints. S2V and Animate are separate workflows, not soundtrack generation in the base model.
Official ComfyUI offload route
TI2V-5B should fit 8GB VRAM with native offloading. The full A14B single-GPU reference asks for 80GB+.
That 8GB statement belongs to the smaller 5B model, not A14B. Quantization, GGUF and compatible acceleration LoRAs can help specific graphs; their quality and requirements differ.
The tradeoff. Lots of flexibility means checking checkpoint, LoRA and workflow compatibility. Do not substitute 5B’s memory needs for A14B’s quality or vice versa.
Official example · Wan-Video / Alibaba
Official family launch reel
Wan 2.2 family · shared T2V A14B / TI2V 5B card reel
Promotional sound · not generated by the silent base model
An approximately 80-second montage, not one generation. The shared reel does not establish which checkpoint made every shot.
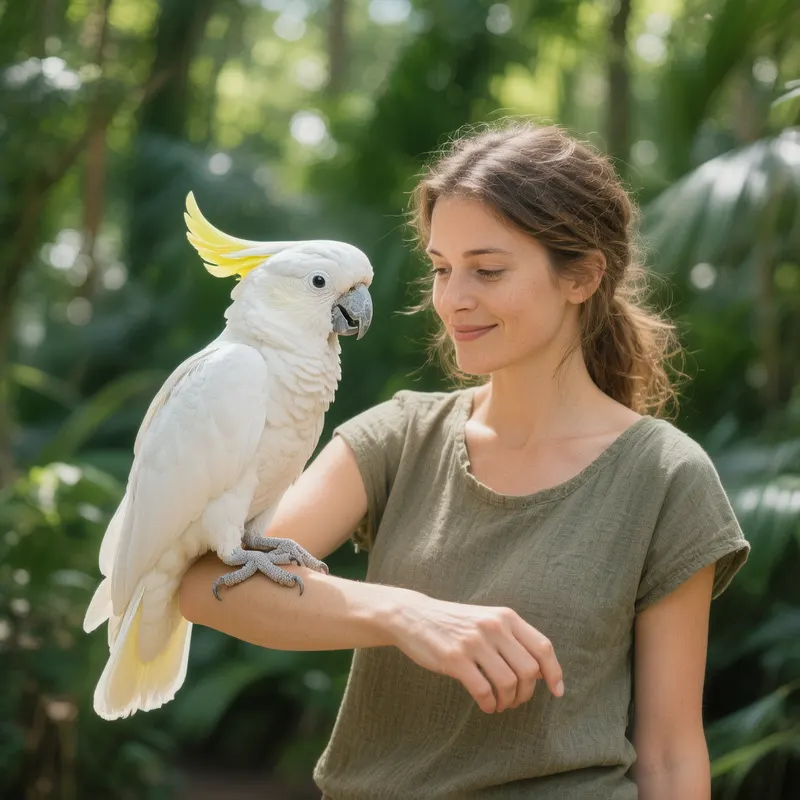
Detailed results from a relatively compact 8.3B model, especially useful for bringing still images to life. The matched input and output below show what that workflow looks like.
An official 10-second 720p benchmark also exists. A hard local maximum is not verified.
Base → later stages
Native 480p / 720p
1080p uses a separate super-resolution stage.
Generated sound
No · silent base
The selected official outputs are silent; add sound in a separate stage.
Reference controls. Text-to-video and image-to-video. The distilled 480p I2V variant uses 8 or 12 recommended steps; that is not a blanket accelerated text-to-video mode.
Official / reference setup
14GB VRAM with model offloading. A separate community WanGP route is described as low as 6GB.
WanGP (formerly Wan2GP) is a different application/configuration. Exact settings, system RAM and platform still matter. Distillation alone does not establish a lower VRAM minimum.
The tradeoff. A strong still-image animation option, but audio and 1080p delivery require other stages. These are official demonstrations, not our own runtime benchmark.
Official example · Tencent Hunyuan
Woman and parrot · image to video
HunyuanVideo 1.5 · exact checkpoint / SR unspecified
A short-form audio-video family with a smaller Lite model and an MIT-licensed core. Lite is about 3B parameters, while Pro is about 29B; they are not the same memory or quality proposition.
These released checkpoints target five-second clips; longer single-pass capacity is not established here.
Base → later stages
SD; official model-card example 864 × 480
HD / Full HD involves a separate video super-resolution (VSR) stage.
Generated sound
Yes · synchronized audio
The family supports generated sound, but both selected published previews are silent. They are not audio demonstrations.
Reference controls. Text-to-audio/video with synchronized sound. Released distilled checkpoints use ten steps; the exact Lite/Pro, distillation and SR settings of the gallery examples are not disclosed.
Documented optimized setup
RTX 5060 Ti 16GB preset: Pro-distill, block offloading and a quantized Qwen encoder.
This does not mean every Pro variant fits fully in 16GB. Lite is a smaller-weight option; no universal tested Lite VRAM floor is established here.
The tradeoff. Short clips, SD base and a newer ecosystem. Core code/model terms do not automatically cover every auxiliary encoder, component or media asset.
Official example · Kandinsky Lab
Desert buggy
Kandinsky 6.0 family · exact variant / SR undisclosed
This published preview is silent
An official visual example, not an audio demonstration. Its 640 × 360 delivery size is not the model’s maximum native resolution.
A checkpoint’s file size is not its peak memory use. Encoders, VAEs, frames, resolution, precision and offloading all affect whether a workflow fits. These are route-specific reports and references, not a universal compatibility chart or a GPU buying guide.
GPU classes and route-specific hardware evidence, not universal minimum requirements.
NVIDIA VRAM class
Model route, evidence level, caveat and sources
Around 8GBNVIDIA VRAM
Official offload workflow
Wan 2.2 TI2V-5B with ComfyUI native offloading.
Only the smaller 5B branch. Hunyuan also has a separate community WanGP route described as low as 6GB; settings and platform matter.
H3’s specific RTX 4070, smaller-encoder / offload configuration.
Qwen3-VL 4B FP8 through ClipProj, a character LoRA and about 40GB system RAM observed, plus shared GPU memory. Not the full original stack or a general guarantee.
Most evidence here is NVIDIA/CUDA. Apple unified memory, AMD VRAM and CPU-only system RAM are not interchangeable with these numbers. No universal Mac, AMD or CPU-only support is promised.
A few terms, in plain English.
VRAM / system RAM
VRAM is memory on your graphics card. System RAM is the computer’s main memory; the two are not interchangeable.
Offloading
Moving components between GPU and main memory to fit a smaller GPU. Usually slower, and it can need substantial RAM or swap.
Quantization
Using lower precision to reduce memory. Quality, hardware and loader support vary.
Distillation / fewer steps
Reducing sampling work. Faster generation does not automatically mean lower peak memory.
LoRA
A small adapter for a subject, style or workflow-specific acceleration. It must match the model and workflow.
I2V / T2V
Image-to-video / text-to-video: starting from an image or a written prompt.
Native / base resolution
The generated canvas before a separate upscaler or refinement stage.
VSR / refinement
A later stage for higher-resolution delivery, not an increase in first-clip duration.
Before you download.
Are these AI video generators really free?
They have downloadable models you can run locally without a vendor charge for every render, subject to their licenses. Your hardware, power, storage and time are not free. Hosted subscriptions, API calls and rented GPUs are separate paid services; this guide does not promise hosted free credits.
Do they all generate sound?
No. H3, LTX-2.5 and Kandinsky 6.0 support generated audio. Base Wan 2.2 and HunyuanVideo 1.5 are silent. Wan’s launch-reel music is promotional sound, while the selected Kandinsky previews and LTX multishot web preview are silent files despite those models’ audio capability.
Which one has an 8GB GPU route?
The official ComfyUI guide says Wan 2.2 TI2V-5B should fit 8GB VRAM with native offloading. This does not apply to full A14B. Hunyuan has a distinct community WanGP route described as low as 6GB. Neither is a guarantee for every machine, OS, resolution or graph.
Can MiniMax H3 run on consumer hardware?
Yes, specific community configurations have results. A 16GB RTX 5080 used pruned INT8 for roughly five-second clips with audio. A 12GB RTX 4070 report used a smaller 4B encoder through ClipProj, a character LoRA and offloading, with about 40GB system RAM observed plus shared GPU memory. That does not prove the unmodified full stack fits 12GB.
Is five seconds a hard limit?
Not for the whole list. H3 publishes a 4–15-second local range. Several other models’ roughly five-second examples are defaults, not verified maxima; Hunyuan also publishes a 10-second benchmark, and LTX has longer workflow-dependent examples. Kandinsky’s listed released checkpoints target five-second clips. A long montage, stitched shots or continuation is not a longer first generation.
Does a 1080p demo prove native 1080p generation?
No. Delivery files, base canvases and refinement stages are different. LTX’s reference 960 × 544 base becomes 1920 × 1088 after latent refinement. Hunyuan uses separate super-resolution for 1080p, and Kandinsky uses VSR for HD/Full HD. H3’s official full 2K recipe includes hosted stages.
Can I use the results commercially?
Terms vary: H3, LTX and Hunyuan use custom community terms; Wan’s core uses Apache 2.0 and Kandinsky’s core uses MIT. Check the actual model license and every component you use, plus rights in inputs and outputs. Model-license labels are not a blanket permission for demonstration footage, music or trademarks. Each model section links its terms.
Where should I start installing?
Choose a route that matches your actual GPU and system RAM, then open that model’s setup guide. The model buttons open official pages rather than starting huge checkpoint downloads. Follow the exact branch’s encoder, VAE, precision and workflow instructions; vendor terms or access gates may still apply. No finished Matt installation tutorial or one-click installer is being offered here.
Workflow details, hardware evidence & sourcesExact variants, further reading and how to interpret the examples.
Research snapshot: October 20, 2026. These five ranks are Matt’s editorial preferences, not an Artificial Analysis leaderboard, equal-prompt test or controlled physics/runtime benchmark. No model installation or generation was performed for this guide. Official examples are curated vendor demonstrations; hardware reports retain their community attribution.
Published model ranges, default frame counts and video-file properties are recorded separately. A web preview’s dimensions or duration do not establish a model’s native resolution or hard limit. Links open official documentation/model pages; actual weight access may still require accepting vendor terms.
#1 MiniMax H3
Comfy-Org supplies pruned INT8 ConvRot, W6A8 and FP8 diffusion choices. A separate encoder and both VAEs are still required. Checkpoint file size is not peak VRAM usage.
The 12GB report’s inspected graph uses 576 × 832, 124 frames at 24 fps (about 5.17 seconds), Qwen3-VL 4B FP8 through ClipProj and a character LoRA. Peak system RAM is roughly 37–39GiB, dedicated VRAM about 10.6GiB, with additional shared GPU memory. It does not establish parity with the original 32B encoder or every reference/audio mode.
A separate RTX 3090 24GB report uses pruned INT8, the original quantized 32B encoder, offloading, about 32GB RAM and 40GB swap for a reported 15-second 832 × 480 stereo-audio output. This is another specific community configuration, not a speed benchmark against the other models.
Experimental 6/8GB reports are not a recommended H3 minimum. Changed components, reduced settings and loader/platform issues matter; capping a 16GB GPU to 8GB is not testing a physical 8GB card.
FastH3 8-Step V2 is an optional speed derivative. Fewer steps do not automatically lower peak VRAM or preserve all reference/audio controls. Hosted H3 Max is a separate product.
Delivered file: 10.13 seconds · 1344 × 768 · audio track present. H3-Base FL2VA · local 768p. Official media source
Omni-reference result · MiniMax
Delivered file: 5.18 seconds · 1344 × 768 · audio track present. H3-Base Ref2VA · local 768p. Official media source
#2 LTX-2.5
The reference two-stage example uses 121 frames at 24 fps, with 960 × 544 base and a separate 2× latent refinement to 1920 × 1088. Do not substitute 1920 × 1080 for those actual dimensions.
Published 16/20-second examples do not establish a universal single-pass ceiling. Frame counts must follow the workflow’s constraints, such as 8k + 1; arbitrary seconds will not work in every graph.
High-resolution/tiled generation and Diffusion Fidelity Rendering are distinct workflows. Neither ‘all native single-pass 4K’ nor ‘all high resolution is just a simple upscale’ describes the whole family.
INT8 ConvRot, NVFP4, distillation and offloading are configuration choices, not interchangeable memory guarantees. The published reference specifies CUDA/NVIDIA; do not assume a Mac or AMD path from the same VRAM figure.
Delivered file: 6.12 seconds · 1920 × 1080 · no audio track. LTX-2.5 · official multishot showcase. Official media source
Rainy intersection · longer multishot example · LTX / Lightricks
Delivered file: 16.09 seconds · 1920 × 1080 · audio track present. LTX-2.5 · official prompting-guide example. Official media source
#3 Wan 2.2
The main model button opens the smaller TI2V-5B model card, not a multi-gigabyte direct download. The full text-to-video A14B and image-to-video A14B weights are separate links below.
Fewer steps and model compression are different optimizations. Acceleration adapters must match the selected model branch and workflow.
Both official media selections are launch montages. Their 80/90-second reel lengths do not describe a single generation, and the shared family reel does not identify every shot’s checkpoint.
Delivered file: 80.04 seconds · 1280 × 720 · audio track present. Wan 2.2 family · shared T2V A14B / TI2V 5B card reel. Official media source
Image-to-video launch reel · Wan-Video / Alibaba
Delivered file: 89.75 seconds · 1280 × 720 · audio track present. Wan 2.2 I2V A14B. Official media source
#4 HunyuanVideo 1.5
The released 480p I2V step-distilled model recommends 8 or 12 steps; 4 steps adds a further quality/speed compromise. It is an I2V variant, not a universal T2V acceleration setting.
The official model card links Wan2GP, whose repository now redirects to WanGP. Its community low-VRAM route is distinct from the documented 14GB offload reference.
The woman-and-parrot still is the input. The matching square clip is the generated output. Exact checkpoint and super-resolution settings for that published example are unspecified; its 960 × 960 file is not a native-resolution specification.
Woman and parrot · image to video · Tencent Hunyuan
Delivered file: 5.04 seconds · 960 × 960 · no audio track. HunyuanVideo 1.5 · exact checkpoint / SR unspecified. Official media source
Soda-can crush · Tencent Hunyuan
Delivered file: 5.04 seconds · 1280 × 720 · no audio track. HunyuanVideo 1.5 · exact checkpoint / SR unspecified. Official media source
#5 Kandinsky 6.0
The family includes Lite (~3B) and Pro (~29B), with synchronized audio, including 44kHz audio. The released five-second checkpoints use 121 frames at 24 fps; distilled versions use ten steps.
The optimized 16GB device preset selects Pro-distill, block offloading and a quantized Qwen text encoder. It is a documented setup, not a fully resident universal minimum or proof of a Lite floor.
The selected official gallery previews are delivered at 640 × 360 and have no audio tracks. Those file properties establish neither the base model’s maximum resolution nor its sound-generation capability. Per-example Lite/Pro, distillation and SR settings are undisclosed.
Delivered file: 5.04 seconds · 640 × 360 · no audio track. Kandinsky 6.0 family · exact variant / SR undisclosed. Official media source
Girl in a glowing forest · Kandinsky Lab
Delivered file: 5.04 seconds · 640 × 360 · no audio track. Kandinsky 6.0 family · exact variant / SR undisclosed. Official media source
Credits: MiniMax, LTX / Lightricks, Wan-Video / Alibaba, Tencent Hunyuan and Kandinsky Lab. Logos may represent a company or model family rather than an individual version. Demonstration footage, music and trademarks retain their owners’ rights; provenance is not a blanket reuse license.
Start with the model’s official setup guide above. A Matt installation walkthrough is not available yet.